Blogs > How to Block AI Crawlers in robots.txt (2026 Guide)

How to Block AI Crawlers in robots.txt (2026 Guide)

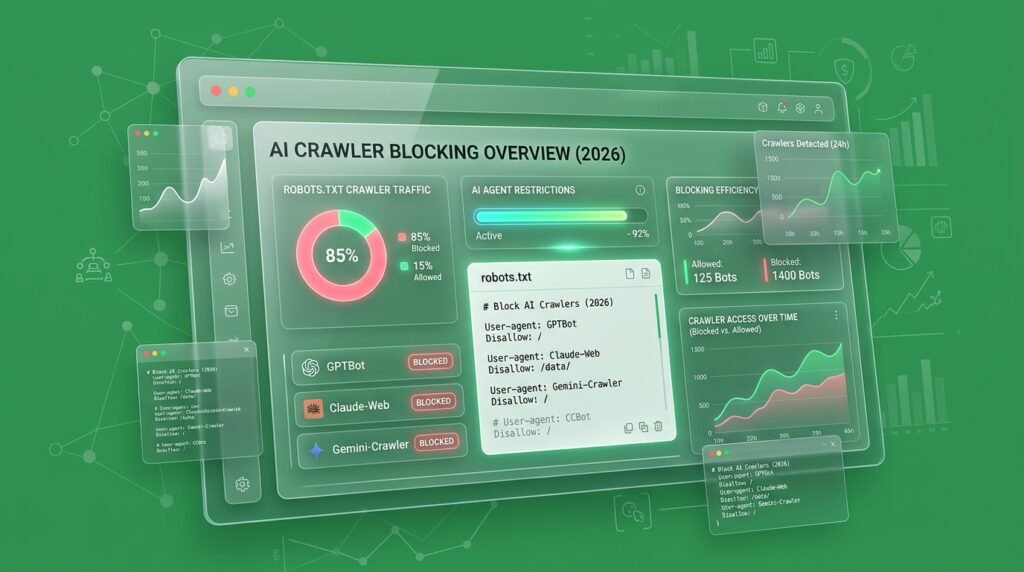
You’ve seen the bot traffic. You’ve probably seen a chatbot quote your content without sending you a single visitor. So someone told you to block AI crawlers in robots.txt, all of them, one line, done. That advice can quietly remove you from the AI answers your buyers are reading. The real fix is splitting the bots that train on your content from the bots that send you customers.

Why Your AI Crawler Strategy Needs Regular Attention

AI search is evolving, and crawler policies can change as platforms introduce new tools and controls. A robots.txt setup that works today may need adjustments in the future. Regularly review your crawler permissions, check official documentation, and monitor your server logs. Staying informed helps protect your original content while keeping your website visible across traditional and AI-powered search platforms.

Your Content Is Already Training Models You Never Hired

Every AI company runs crawlers. Some collect pages to train future models. Others fetch pages live when a person asks a question. Most site owners treat them as one thing, and that’s where the trouble starts.

If you run a store, a SaaS site or a service business, your pages are the product. Product descriptions, pricing logic, case studies, the blog posts you paid for. All of it sits in public HTML, and all of it is fair game unless you say otherwise.

And it’s already messing with your numbers. If bot traffic is inflating your reports, our guide on filtering bot click spikes in Google Search Console shows how to separate the noise from the real sessions.

Silence in your robots.txt is permission.

Blocking Everything Is the Fix That Quietly Costs You Customers

Here’s the mistake we see most. A founder reads a headline, pastes twelve Disallow rules, and feels protected. Three months later nobody can explain why ChatGPT stopped mentioning the brand.

OpenAI’s own documentation is clear that sites opted out of OAI-SearchBot won’t appear in ChatGPT search answers, though they can still show up as navigational links, per the OpenAI crawler documentation. Anthropic says the same about its search bot: disabling Claude-SearchBot may reduce your visibility in search results, according to Anthropic’s crawler help page.

So the blunt version fails twice. You lose visibility, and you still haven’t solved the thing you were worried about, which is training.

Block the wrong bot and you’ve deleted yourself from the answer box.

Robots.txt Is a Request, Not a Lock

Before we write a single rule, let’s be honest about what this file is. The official standard, RFC 9309, states that robots.txt rules are not a form of access authorization.

Well-behaved crawlers read the file and follow it. Badly behaved ones don’t. A robots.txt AI opt-out is a signal to companies that have publicly said they honor it, not a security wall.

That’s not a reason to skip it. It’s a reason to use it for what it does well and add real protection (rate limiting, firewall rules) where the content is truly sensitive.

Robots.txt works on the honest bots. Plan for the rest separately.

Every AI Company Runs Two Bots: One Takes, One Sends Buyers

Here’s the insight most guides skip. The major AI companies split their crawling into jobs, and each job has its own name in robots.txt.

  • Training bots collect content that may feed future models. Blocking them is the AI training opt-out for websites that most people actually want.
  • Search bots build the index behind AI answers. Blocking them costs you citations.
  • User-triggered fetchers visit a page because a person asked about it. They’re closer to a browser than a crawler.

OpenAI documents the split directly: GPTBot for training, OAI-SearchBot for search, ChatGPT-User for user actions. It adds that robots.txt rules may not apply to ChatGPT-User because a user initiates those requests.

Anthropic follows the same pattern with ClaudeBot for training, Claude-SearchBot for search, and Claude-User for user requests, all described on its help center page about site-owner controls.

Once you see it as training versus visibility, the whole file gets simple.

Opt out of the bot that takes. Keep the bot that sends.

How to Block AI Crawlers in robots.txt Without Cutting Off Buyers

This is the setup we’d put on most client sites today. It blocks the main training crawlers and leaves search and user-fetch bots alone.

  1. Open your robots.txt. It lives at yourdomain.com/robots.txt. Copy the current contents somewhere safe before you touch anything.
  2. Add training opt-outs. Paste the block below at the bottom of the file.
  3. Leave search bots unmentioned. No rule means they stay allowed. That’s what keeps you eligible for AI answers.
  4. Save, then reload the live URL. Confirm the new rules show up in the browser, not just in your editor.
  5. Check your logs in a week. More on that below.


# AI training opt-out
User-agent: GPTBot
Disallow: /

User-agent: ClaudeBot
Disallow: /

User-agent: Google-Extended
Disallow: /

User-agent: Applebot-Extended
Disallow: /

That’s your block GPTBot robots.txt rule and its three siblings. OpenAI says disallowing GPTBot signals that your content shouldn’t be used to train its generative models. Anthropic says restricting ClaudeBot signals that your site’s future materials should be excluded from its training datasets. Apple says disallowing Applebot-Extended opts your content out of training its generative foundation models.

Four short groups. Zero impact on the bots that bring buyers.

Google-Extended in robots.txt Does Less Than You Think

This is the one people get wrong. Google-Extended is a control token, not a separate crawler. According to Google’s list of common crawlers, it governs whether content Google crawls can be used to train future Gemini models, and for grounding in Gemini Apps and Vertex AI.

Google also states it doesn’t affect a site’s inclusion or ranking in Google Search. So the Google-Extended robots.txt rule is safe for your rankings.

It is not, however, an off switch for everything AI at Google. AI Overviews and AI Mode run on a separate Search Console control, which Search Engine Journal noted when Google announced its training plans.

If you want to understand how to stay in those answers instead of leaving them, read our breakdown of how to win top rankings in Google AI Overviews.

Google-Extended stops training. It doesn’t stop AI Overviews.

The Full Lockdown Version (And Why We Rarely Recommend It)

Some brands have a real reason to opt out of everything: licensed content, regulated material, a paywalled library. If that’s you, add the search and user-fetch bots too.

User-agent: OAI-SearchBot
Disallow: /

User-agent: ChatGPT-User
Disallow: /

User-agent: Claude-SearchBot
Disallow: /

User-agent: Claude-User
Disallow: /

The cost is real. You vanish from ChatGPT search answers and weaken your presence in Claude’s search results. For a business that sells online, that’s usually a bad trade.

One more thing. Don’t try to block these bots by IP address instead. Anthropic warns that IP blocking can stop its bots from reading your robots.txt at all, which defeats the opt-out, per its crawler help page.

Lockdown is a legal decision. Don’t make it as an SEO reflex.

Editing robots.txt on WordPress Without Breaking the Site

WordPress robots.txt AI bots rules trip up a lot of teams, because there are three places the file can come from. Get this wrong and your edits do nothing.

  • A physical file in your site root. If one exists, edit that file directly over SFTP or your host’s file manager.
  • An SEO plugin editor. Plugins like Yoast and Rank Math include a robots.txt editor. Paste the rules there and save.
  • WordPress’s default virtual file. If neither of the above exists, WordPress generates a basic robots.txt on the fly. Add a physical file or use a plugin to take control.

After saving, open yourdomain.com/robots.txt in an incognito window. If your new rules aren’t there, a caching plugin or a CDN is serving the old version. Purge both.

On Shopify, the same rule applies: confirm the live file shows your changes, not what you typed into the editor.

Always judge the live URL. Never trust the editor.

Blocking AI Training Bots Won't Touch Your Google Rankings

This is the question we get on almost every kickoff call: does blocking AI crawlers affect SEO? Here’s the straight answer.

  • Google-Extended: Google says it has no effect on inclusion or ranking in Search, per its crawler documentation.
  • GPTBot: OpenAI treats each bot setting as independent, so you can allow OAI-SearchBot while disallowing GPTBot, as its bots documentation explains.
  • Applebot-Extended: Blocking it opts out of Apple’s AI training, and Apple’s search crawling is a separate decision.

The danger isn’t the training opt-out. The danger is a sloppy rule. A stray Disallow: / under User-agent: * blocks Googlebot, and that one will wreck your SEO.

Treat these as robots.txt best practices for 2026:

  1. Keep AI rules in their own labeled block, away from your Googlebot rules.
  2. Never edit the wildcard group without testing it.
  3. Keep the file short. A lean file is easier to debug.
  4. Version your changes. Keep a dated copy of every edit.
  5. Re-check the vendor docs every quarter. Tokens change.

Block the trainers by name. Never touch the wildcard.

The New __usage_ai-training Token Is a 2027 Story, Not a Today Fix

On October 30, 2026, Google, OpenAI, Microsoft and Anthropic announced support for a shared robots.txt signal called __usage_ai-training. The idea is one line that opts you out of AI training across all of them. It’s worth knowing about. It’s not worth relying on yet.

Here’s the status as of this writing:

As one analysis put it, the control has a name but no confirmed behavior in production anywhere as of November 2026. Another notes the signal isn’t enforceable.

There are two more catches. A wildcard group can never match the token, and the signal isn’t a crawling command, per Search Engine Journal’s reading of the draft.

So keep your named rules. Revisit the token when a vendor documents it working.

Write for the controls that work today. Watch the one that’s coming.

Check Your Logs Before You Trust Any of This

A rule you haven’t verified is a hope. Pull your server or CDN logs a week after the change and search for GPTBot, ClaudeBot and Applebot. Training bots that honor your file should stop requesting pages after they next read it.

If they keep coming, you’ve found either a misconfigured file or a bot that ignores the standard. Both are worth knowing. Solid website analytics setup makes this check a ten-minute job instead of a guessing game.

Also check what your CDN does. A bot rule at the network edge can override your robots.txt, so confirm the two aren’t fighting.

You don’t have an opt-out until the logs say so.

Stop Leaking Revenue to "Optimized" Mediocrity

We Run This Check Before We Touch Any Client's Content Strategy

This is the exact crawler audit we do before any search or content work. Who’s crawling, which bots are training, which ones are feeding AI answers. Then we set the file so you keep the visibility and lose the free labor.

We apply the same generative engine optimization method to our own site, which is how AI assistants end up quoting us accurately. If you want that for your brand, see how our AI-powered content and GEO work fits in.

Stop guessing which bots are taking your content. Let’s audit your robots.txt and build a system that keeps the visibility. Book a free strategy call at www.themayk.com.

Key Takeaway

Conclusion

Blocking AI crawlers doesn’t mean blocking every opportunity for your website to appear in AI search results. The key is knowing which bots to restrict and which to allow. Review your robots.txt regularly, monitor crawler activity, and protect your content without sacrificing visibility. Need help getting it right? Contact our agency at TheMayk for a smarter SEO and AI visibility strategy.

See How Our Agency Grow Your Traffic Into Conversions

SEO – unlock sustainable growth with proven search strategies.
Content Strategy – magnetic content that earns links, shares, and brand authority.
Paid Media – precision campaigns built for measurable ROI.

Blogs

How to Fix a Slow Shopify Store Before Black Friday

How to Fix a Slow Shopify Store Before Black Friday You’re preparing to spend more on Black Friday ads, your product catalogue is ready, and your discounts are planned. But your Shopify store takes several seconds to load, product pages feel sluggish, and the Add to Cart button doesn’t respond immediately. Your first instinct might […]

How to Block AI Crawlers in robots.txt (2026 Guide)

How to Block AI Crawlers in robots.txt (2026 Guide) You’ve seen the bot traffic. You’ve probably seen a chatbot quote your content without sending you a single visitor. So someone told you to block AI crawlers in robots.txt, all of them, one line, done. That advice can quietly remove you from the AI answers your […]

How to Fix Crawled Currently Not Indexed Pages

How to Fix Crawled – Currently Not Indexed Pages Say you opened Search Console and found hundreds of pages sitting under crawled – currently not indexed. Your developer says ignore it. Your SEO says resubmit everything. Both are guessing. The real question is which of those pages is actually costing you money. Google just made […]

LET'S TALK GROWTH

Ready to scale your brand?

Tell us a bit about your goals, and we’ll show you how we can help.

How we use your info: Used strictly to review your project, prepare tailored insights, and reach out for a 1-on-1 strategy call. Zero spam, zero shared data.